
https://learn.microsoft.com/en-us/windows/win32/intl/character-sets-used-in-file-names
"Character Sets Used in File Names
NTFS stores file names in Unicode"
MICROSOFT
MICROSOFT, THAT IS INADEQUATELY SPECIFIC
Discussion
https://learn.microsoft.com/en-us/windows/win32/intl/character-sets-used-in-file-names
"Character Sets Used in File Names
NTFS stores file names in Unicode"
MICROSOFT
MICROSOFT, THAT IS INADEQUATELY SPECIFIC
@mcc "In contrast, the older FAT12, FAT16, and FAT32 file systems use the OEM character set." WHICH ONE
@typeswitch THAT WOULD BE THE THIRD OPTION
@mcc well at least it isn't mysql utf....
> Pulling up the filesystem documentation
> Ask the OS vendor if the filenames are UTF-16 or UCS-2
> OS vendor doesn't understand
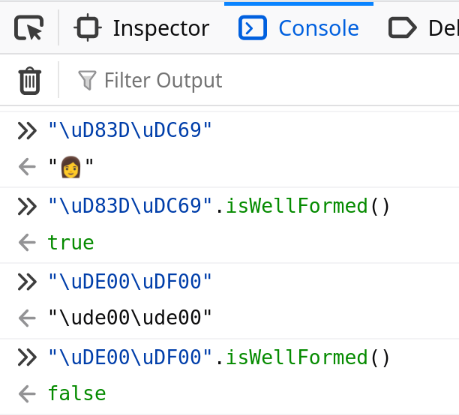
> Pull out illustrated diagram explaining what is UTF-16 ([0xD83D, 0xDC69]) and what is UCS-2 ([0xDE00, 0xDF00])
> Microsoft laughs. "It's Unicode"
> Inspect the bytes on the disk
> It's UCS-2
@mcc arguably UCS-2 ceased to exist the moment UTF-16 was invented and every system formerly using UCS-2 de-facto became "UTF-16 without well-formedness checking". WTF-16, although that name didn't exist yet
@mcc I mean, the file system doesn't care. Other platforms don't enforce valid UTF-8 either. (Except I think macOS because once upon a time they changed everything to normalization form D)
@malwareminigun i don't care if the filesystem cares but if the filesystem doesn't care the documentation should not say things like "NTFS stores file names in Unicode" without qualification!!
@mcc I mean, technically it's not UCS-2 as that encoding makes surrogate code units illegal as of the last standard.
@chrisdenton Hm. Would that have been true at the time the NTFS standard was created
( I have been reminded that "sequences of uint16_t which are interpreted as UTF-16 if they are valid UTF-16, but are not necessarily valid UTF-16" has been alternately given the proposed name "WTF-16"; https://wtf-8.codeberg.page/ This is an informal designation, but since no one actually ever *has* attempted to come up with a formal designation, "WTF-16" is probably a more accurate descriptor of what Microsoft is doing here.
However, I hate this thing about case folding https://girlcock.club/@olives/117584077114879976 )
@mcc it's a long standing footgun in the Windows platform
https://devblogs.microsoft.com/oldnewthing/20241007-00/?p=110345/
@mcc oh yeah, I remember that I hate that, especially dealing with Win32 API. Thanks for the (ugly) flashback, the WTF-16 is much more accurate indeed
Illustrated diagram explaining what is UTF-16 and what is WTF-16
@mcc
Both NTFS and MSSQL seem to be vague on this point.
@mcc it is going to be UCS-2 validation just makes you need error handling:)
@blinkygal @mcc Wikipedia claims Windows uses UTF-16. https://en.wikipedia.org/wiki/UTF-16
UCS-2 is now obsolete and dropped from the Unicode standard. But Windows was definitely all UCS-2 back in the NT / W2K era.
@hyc @blinkygal Sorry when I say "is it UCS-2 or UTF-16" what I mean is "Is it valid UTF-16 or potentially-valid UTF-16, and also is any kind of normalization scheme in effect ever"
@mcc back when NTFS was created, UTF-16 didn't exist. And there were no defined character codes outside the 16 bit character space.

















@mcc /me is reminded yet again of the infuriating manager claiming something is "plain text".