
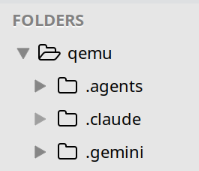
Going to try to make some small UX patches to qemu. They actually have a policy banning submitting code written by "AI" but it sure does feel a bit 😬 that the entire time I have this thing open in Sublime the upper left corner of my screen looks like this
0 Boosts
0 Likes


@mcc without looking at the source folder, I'd hazard a guess that they were written before AGENTS.md became a de facto standard that they actually follow across the board.
@trechnex That's a good guess, but my sense is that COPILOT.md and CLAUDE.md appeared first, THEN AGENTS.md, THEN after AGENTS.md was an established standard I've started to see "skills files" crop up VERY recently only. Presumably if I looked up what a "skills file" is I'd understand quickly but I am not sure I really want to know

@mcc this is something i really want to build for ngscopeclient
@azonenberg just write it! sit down with something like Sublime Text or the os x "finder" that lets you click a > to expand a folder, look at the first two levels of the folder hierarchy and write down what each thing does. then look at what you wrote and ask "how much of this is obvious? how much would be useful to leave around for other contributors?"
or do you mean you want ngscopeclient to learn to generate them somehow lol
@mcc it's not folder hierarchy, that's pretty simple (although adding more levels might help).
What needs writing is basically the internal architecture, like how the various components in the data model relate to each other and what they do etc.
Not like api documentation but a step or two above that.
And some guides on how to write a new protocol decode, instrument driver, etc


@mcc oh, I do this with my own development documentation so I can find my way around. Markdown files in obsidian, with a navigation section at the top of a unifying `start-here.md` file with "You have -> Go here...". Definitely saves enormous time.
@GavinChait shocking how few programmers realize that writing down something that helps a new-to-the-project contributor is going to help *you yourself* after you put your own project away for two years and come back to it
@mcc sheesh, I can't bear the frustration of being lost in my *own* code, let alone someone else's.
…that's the exact kind of information in these skills/claude.md/agents.md files?
Realizing with sinking horror it's actually in my interest to read these files. But inexplicably there are five different files, implying somehow Claude, Copilot, and Gemini all prefer SLIGHTLY DIFFERENT massaged text, and I need to read all four files to understand the actual shape of the repo, and in the process I'll come to indirectly understand the nuances between those four products. Ugh

@mcc Our agents.md is a better style guide than our actual style guide and it drives me *nuts*.
@mcc AI users have very strong superstitions about how to properly prompt their preferrred... pmodel, but i am not convinced there is any truth to it
Wait, hold on, if the project has five different files containing verbose human text that are are largely duplicative, does that implies the skills/claude.md/agents files were themselves written with genai

@mcc yes, they often basically serve as a "cache" so agents don't have to re-ingest all the same stuff to figure out the basic shape and structure of the codebase


@mcc It is very common to write these files by hand initially but then have the tool update them after any sufficiently complicated interaction.
It offends me but descriptively it works pretty okay-ish.


@mcc To my understanding, the workflow for people who have some programming knowledge often starts by having a conversation with the chatbot specifying the structure and requirements of the user. So yeah, those files are almost certainly a genAI compilation of those conversations mixed in with things that were referenced as external sources of those requirements, and any planning done in that phase.


@mcc my understanding (based on very limited testing a while ago) is that if someone uses an LLM agent, its default behavior is to edit the AGENTS.MD/etc. files constantly. It is very likely the majority of those are LLM-generated

@mcc … all the way down? At least that's how it sometimes feels like atm.

@mcc and you're right that each of the models has its own specifics around optimal instruction language, which also changes somewhat between major releases. it's partly related to training approaches and system prompts in the harnesses, but also because those agent files often get tailored to avoid specific failure modes in a model, even if the user writing (or instructing the writing of) the agent file doesn't recognise it as such.
@gsuberland@chaos.social @mcc@mastodon.social but also slowly everythings converging to AGENTS.md because Anthropic gave up on CLAUDE.md
@erincandescent @mcc which is actually sorta silly because of the model prompts actually need to be different in a lot of cases due to variances in the model design and tooling integration.


@mcc yes, absolutely. Most “skill” files I’ve seen are very much slop-generated. But, alas, they do tend to be somewhat useful to look at, since they tend to have quite detailed and recent info.

@mcc Quite possibly… the machine is documenting what it has produced.
@mcc guilty as charged, and I have no idea what to do about it :-(
@glyph As penance, immediately open a text editor and create the following two files in your Twisted working copy:
- contents.txt: Toplevel directories and important subdirs and a human readable description of each. For example https://github.com/mcclure/emily/blob/93b42a12fd8fed4c54089d55eaa889d8b7896d86/contents.txt#L9 or https://github.com/mcclure/lovr-ent/blob/d5a1e552e64d661c0656a628552c765be4ef0506/lua/contents.txt#L74
- run.txt: What commands do you actually have to type into Bash to create a local deployment, to create a package for distribution, or to run the tests? In python the first may be trivial, but I doubt the third obvious

@mcc
If you're doing run.txt, why not https://mise.jdx.dev/tasks/ with comments, to make them actually executable?
@glyph
@mcc The README includes some of these things, but others of them are torturously complex to write down, particularly because "a deployment" is such a flexible concept in this context that it dissolves into meaninglessness
@glyph Here's an example of what I mean by run.txt
https://github.com/mcclure/rs-hello/blob/3a0cb370e9e46a5d3689a5eca6d1285b71f1716a/run.txt
Often one spends so long on a repo one finds it "obvious" that (cd site && python3 -m SimpleHTTPServer) is how you boot a local test, but it's very much not obvious to someone who hasn't worked on the project before.

@mcc Oh yes, so much this.

@mcc Surely those contain instructions for the chatbots to fuck off, right?
@mlen Well, now that you mention it, they do begin with an exhortation that the chatbot must only participate in the repo in accordance with the AI policy (which is quite strict that the AI can only be used for querying information about the repo or for non-committed experiments). But I severely doubt this is the kind of instruction an AI bot can meaningfully follow.

Thinking about it…
Few open source projects have contributor documentation, and the missing thing that always frustrates me most is the lack of "structural documentation" (I call it this, idk what else to call it). I always spend so much time trying to figure out WHERE TO FIND THINGS. I want to know where in your directory tree the argument parsing is, the menu building is, the rendering code. You don't tell me and most project src/ trees grew organically and not according to any true logic.